Scraping Agency
Web Scraping consists of automatically extracting data from one or more sources on the internet. Scraping uses are very numerous and can present many advantages for companies.
Our Scraping Services
Web Scraping consists of automatically extracting data from one or more sources on the internet. Scraping uses are very numerous and can present many advantages for companies.
Automatically monitor competitor product prices in real time
Extract online reviews to feed custom AI models
Build qualified lead databases to fuel prospecting
Identify technologies and tools used by companies to offer them adapted services • And many other use cases!
Calling on a scraping agency like Terros allows you to significantly reduce the complexity and delays associated with setting up scraping programs.
Our Approach
Advanced Technical Expertise
Our team masters bypassing the most sophisticated anti-bot protections. We handle large volumes with scraper deployment on stable and scalable cloud infrastructures.
We also automate complex authentications when necessary, with multi-step token generation and in-depth analysis of login systems.
Compliance & Ethics
We guarantee strict compliance with GDPR and best practices. Our reasoned orchestration of requests does not overload target servers. We adopt a responsible approach to data collection, in full compliance with current regulations.
Flexible Delivery Formats
We offer exports adapted to your needs:
CSV, JSON export for analysis in your existing tools
Real-time API for direct integration into your systems
Direct integration into your analysis tools (CRM, BI, databases)
One-time delivery or continuous flow according to your operational needs
AI Analysis of Collected Data
Beyond simple extraction, we offer advanced analysis services:
Integration into semantic analysis tools SaaS or on-premise (OpenWebUI, Langchain...)
Automated analysis pipelines for insight extraction: sentiment analysis, trend detection, thematic clustering
Building knowledge bases queryable in natural language for your teams
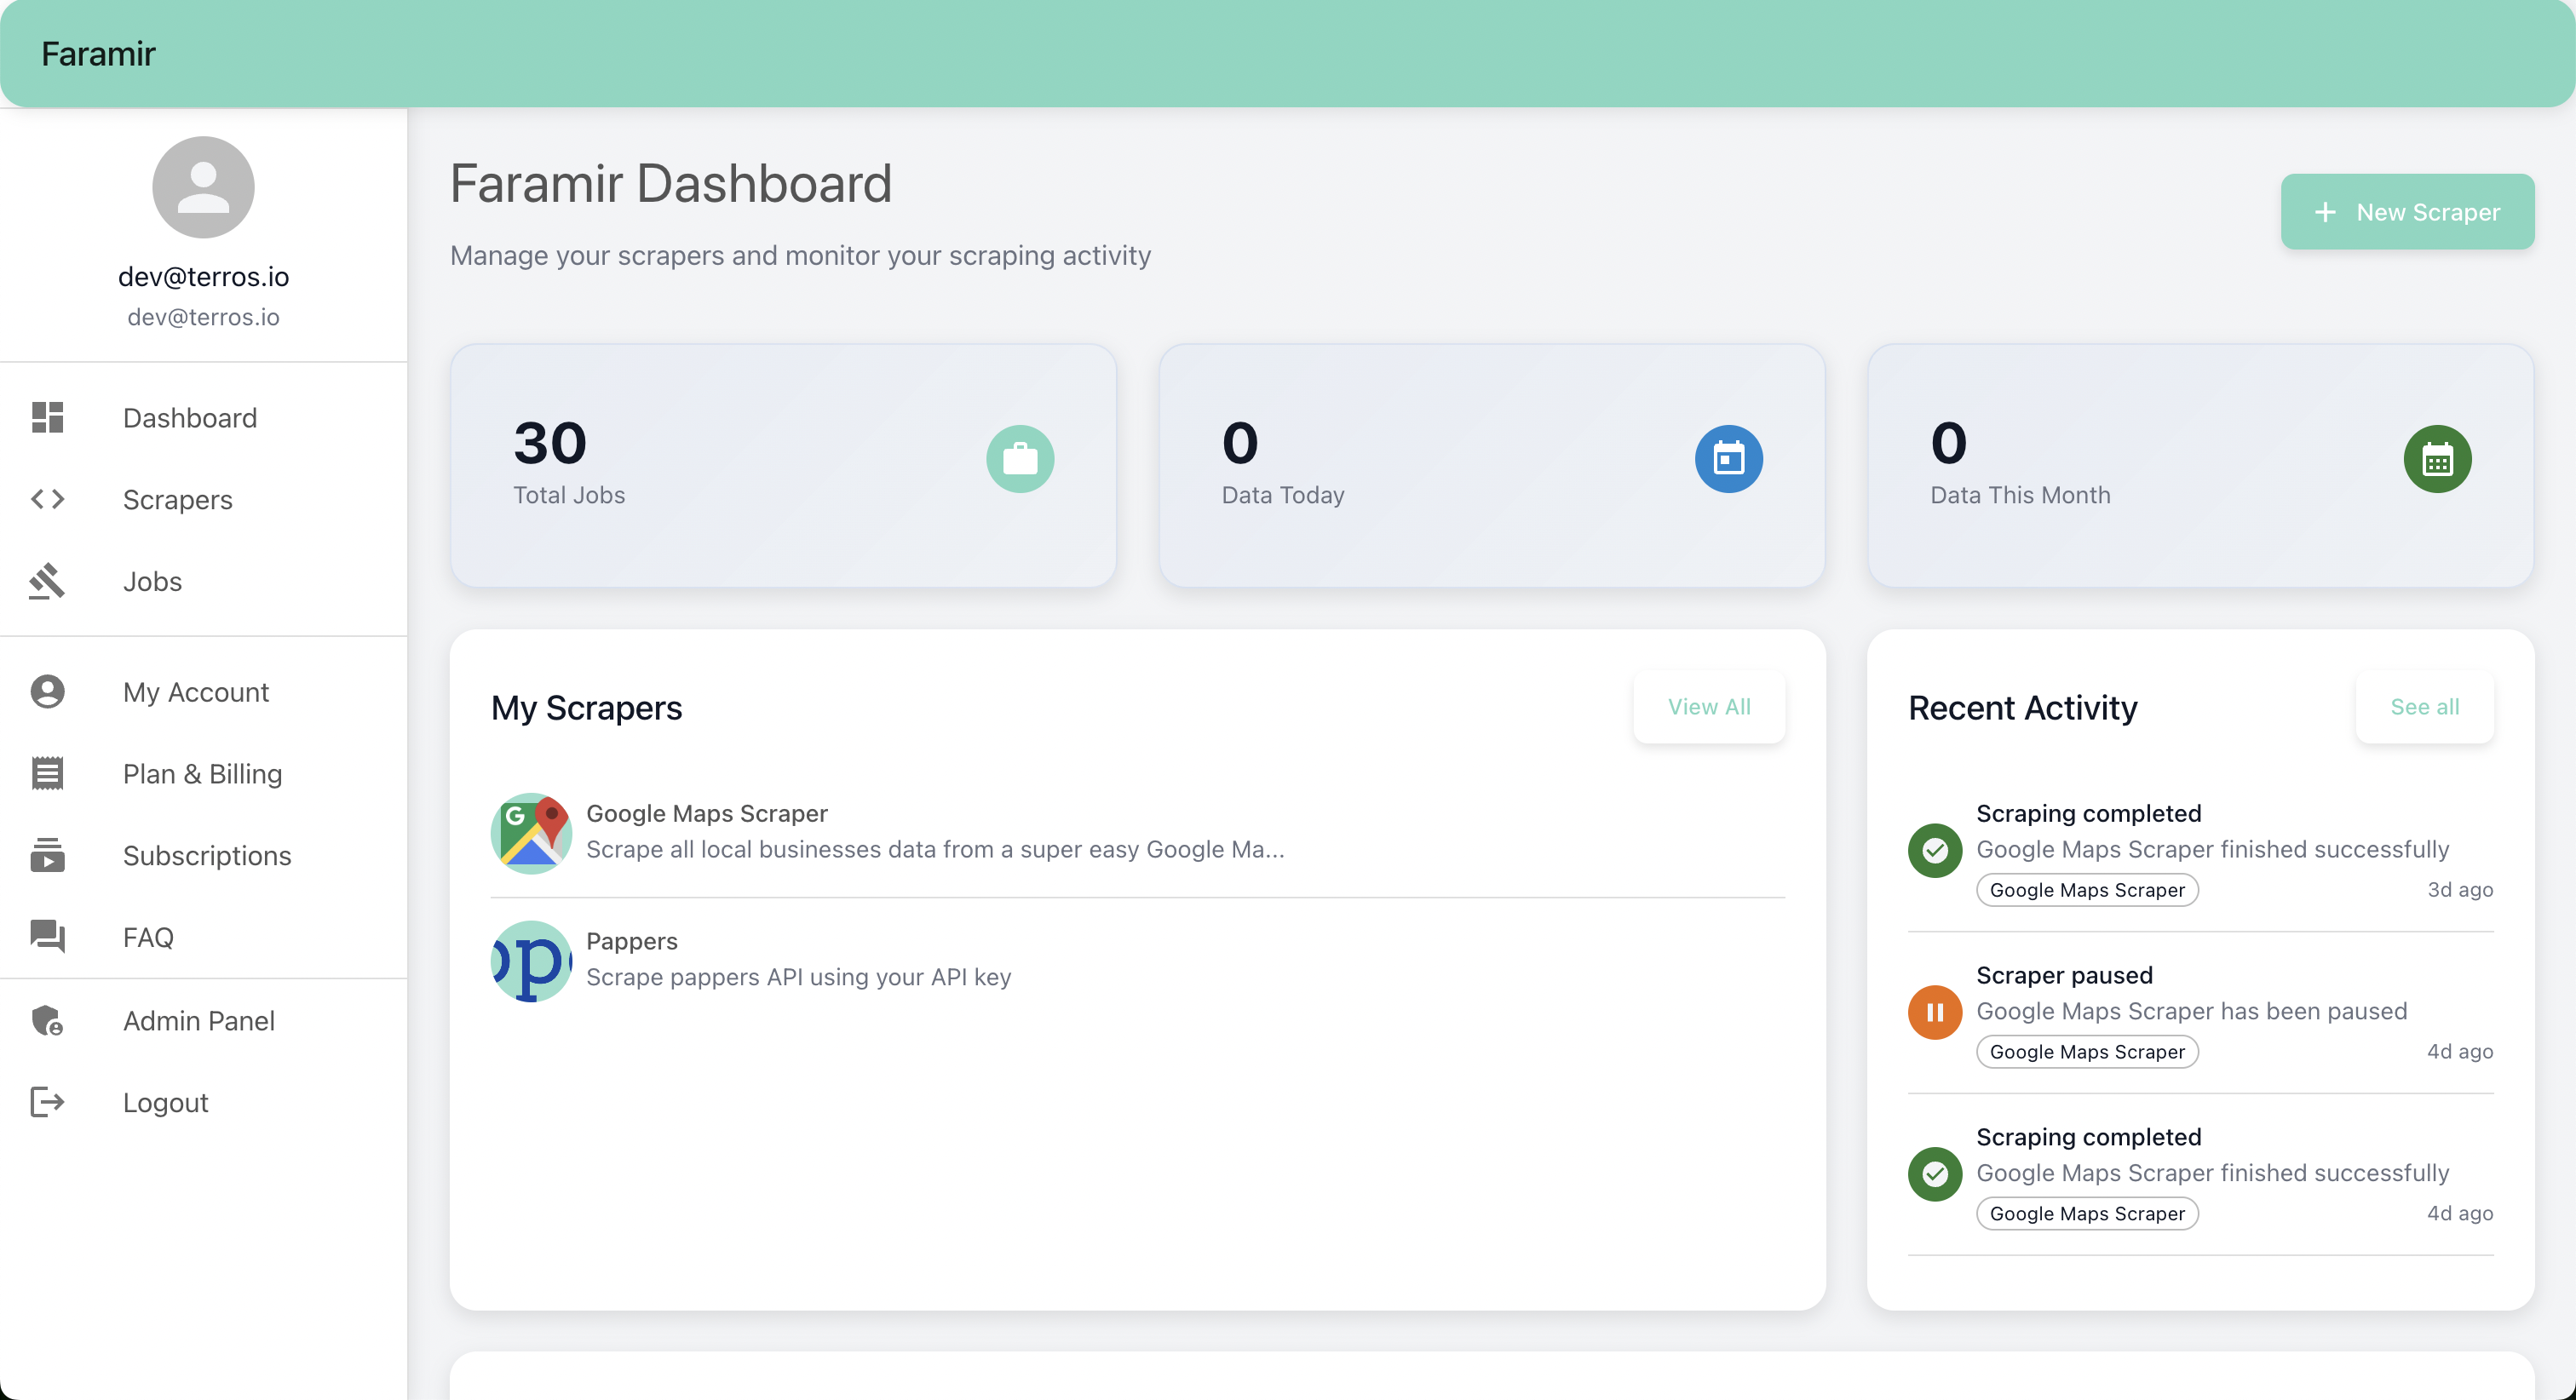
Faramir: Your Autonomous Scraping SaaS Platform
We created Faramir, a SaaS platform that allows our clients to access their scrapers with complete autonomy, whether off-the-shelf or custom-developed. You can manage your extractions, schedule your collections and monitor your scrapers directly from an intuitive interface.
Our Scraping Development Method
Setting up Web Scraping algorithms requires careful preliminary audit as well as understanding data extraction needs.
Understanding Requirements and Objectives
Our team of Web Scraping experts and Product Managers analyzes your needs and the different characteristics of your business to propose an automation scenario, allowing you to understand and contribute to the different stages of the project, its budget and schedule.
Identification of Most Relevant Sources
Based on identifying your needs, we establish with you a list of the most relevant web sources to target.
Detailed Audit
It is essential to carry out an audit of sources before setting up one or more Web Scraping processes to guarantee the legality, ethics and technical viability of data collection.
A thorough audit allows evaluating legal compliance with laws and terms of use of targeted sites, identifying potential technical limitations, and ensuring that Web Scraping respects ethical standards and best practices. By understanding source characteristics, we minimize legal, technical and ethical risks, and ensure effective and responsible data collection.
Data Architecture Design
Our team of architects ensures the planning of the structure in which collected data will be stored. This includes defining data types, relationships between entities, and choosing appropriate databases or storage systems.
Thoughtful data architecture design ensures effective organization, facilitated information retrieval and optimal management of the growing volume of data collected via web scraping.
Prototyping and Development
Initial scraping scripts are developed to test technical feasibility and evaluate the quality of extracted data.
In the development phase, these prototypes are improved, optimized and adapted to be robust against potential changes on targeted sites. This step is crucial to ensure the reliability and stability of the Web Scraping process while respecting ethical and legal constraints.
Deployment and Monitoring
Our DevOps team trained in specific Scraping issues ensures if necessary the deployment of different Web Scraping modules developed on an adapted Cloud architecture.
This deployment allows for example to ensure regular and autonomous data extraction to guarantee permanent monitoring of targeted sources and continuous feeding of various databases: prospect lists, price matrices, machine learning models...
Our Scraping Expert Team
As a Scraping agency, we provide you with our team of versatile experts who are adept at the latest technologies to design custom Scraping solutions.

Jeremy
Product Manager – Ecommerce specialist

Salima
FullStack Developer

Alexandre
Lead Developer

Augustin
Architect Developer

Ayoub
AI Developer
Our Scraping Achievements
Discover how we helped our clients transform their processes thanks to Scraping
Advantages and Disadvantages of Scraping
Discover the strengths and challenges of Scraping
Advantages ✅
Accuracy and consistency
Scraping robots eliminate human errors and ensure consistent and accurate data collection, even on very large volumes.
Efficiency and time savings
Scraping allows automating data collection that would take hours or days to do manually, thus freeing up time for more strategic tasks.
Scalability
Scraping can process thousands of pages simultaneously, allowing efficient large-scale data collection.
Disadvantages ❌
Legality and ethics to master
Scraping must respect website terms of use and current regulations (GDPR, copyright). Poor practice can lead to legal consequences.
Technical complexity
Developing scraping robots requires advanced technical expertise and constant maintenance to adapt to changes in targeted sites.
Resources used and Cost
Intensive scraping can consume a lot of server resources and bandwidth, generating significant infrastructure costs to process large volumes of data.
Frequently Asked Questions about Scraping
Everything you need to know about our Scraping services